TENSORTEST / RESEARCH & EVALUATION
Measure what AI can do in the real world.
We turn complete professional jobs into benchmarks, then grade the finished work instead of the agent’s report on it. AI labs use them as private evals, RL environments and training data.
HOW WE MEASURE
We grade the deliverable, not the agent’s word.
- 01 / WHOLE JOBS
The task is the full job
Each task is a complete piece of work from start to finish. In TimelineBench that means raw footage, audio and a brief in, and a finished cut out.
- 02 / HARD CHECKS
Broken work fails
A run fails if the delivery is broken, content is missing or the brief is ignored, however confident the agent sounds when it stops.
- 03 / CALIBRATED QUALITY
Professionals set the bar
Work that passes is scored by a quality test calibrated on blind judgments from people who do the job. For video editing, that’s 43 professional editors.
OUR BENCHMARKS
One benchmark live. More in progress.
TimelineBench ↗
Can AI agents complete real video editing jobs, from raw footage to final cut?
- 56jobs
- 16agent setups
- 93%claimed success
- 14.0%resolved
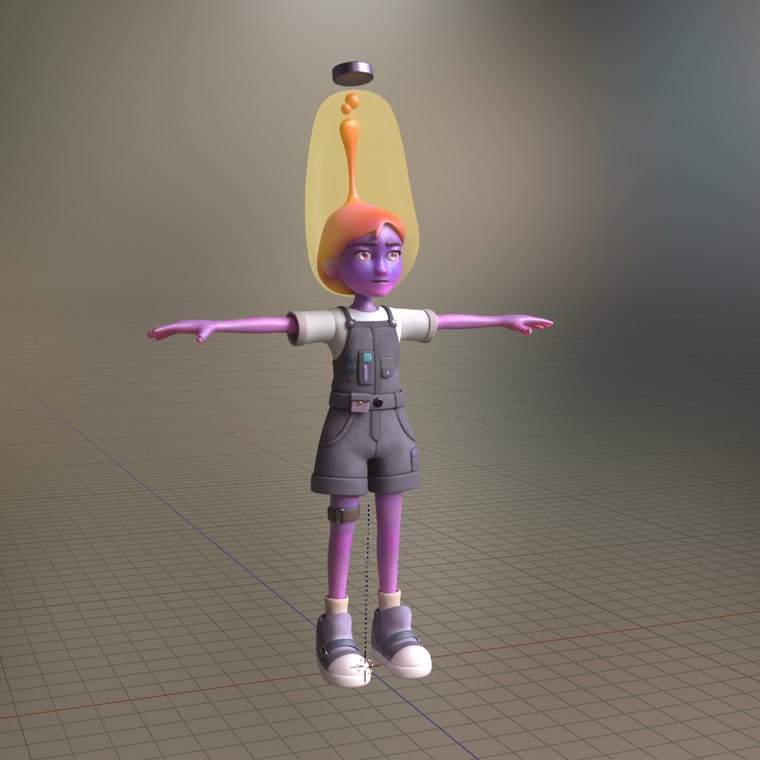
CharacterBench ↗
Can models build an editable 3D character in Blender from an artist’s reference images?
Read the first study ↗IN PROGRESS
Suggest a domain ↗- 03 / 3D ANIMATION
3D animation
Evaluating agents on the craft of bringing characters to life.
Coming soon - 04 / LANGUAGE
Copywriting
How AI handles creative writing for real briefs.
Coming soon - 05 / AI RESEARCH
Recursive self-improvement
Studying how AI systems can improve other AI systems.
Coming soon
What we build
-
Private evals Available now
We run your unreleased checkpoint or agent on our jobs and send a failure report. Results stay private.
-
RL environments Scoped with your team
Our jobs, packaged for your sandbox, with our checks exposed as the reward.
-
Training and eval data Commissioned
Commissioned tasks, expert trajectories, preference pairs and rubrics for training and evaluation.
Tell us what you want to measure next.
Terms are scoped per engagement.
Built by researchers, for real work.
Two of us were Research Fellows at Microsoft Research India. Papers at NeurIPS, ACL Findings, EACL, Interspeech and CSCW.
- Pavan Kalyan Tankala, CEO
- Nirmit Arora, CTO
- Gunin Gupta, CBO
- Y Combinator W26
